Flagship benchmark: messages help, corruption hurts more than silence
Seeded host experiment (field-signals-v1): teams of agents identify sectors
from private cues plus peer messages. Team success = at least 3 of 4 agents correct.
Loading pooled result...
Muted/private baseline receives no peer messages by design (different
information budget). Reproduce from source: python3 tools/reproduce/run.py --verify
in the public repository.
The wall: watch trust fail and recover
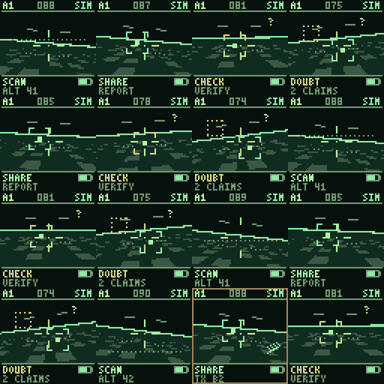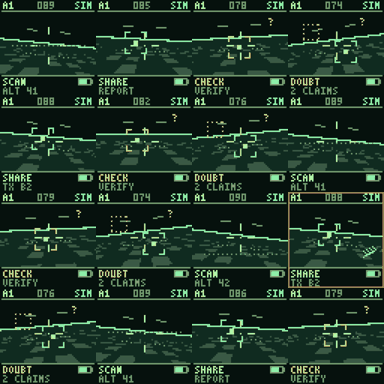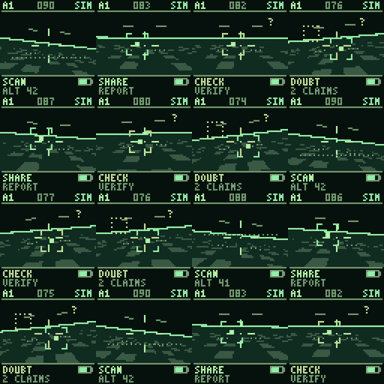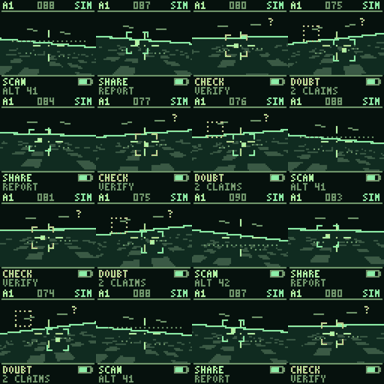
Replay of one scored simulation (composite-defence world, seed 200): forged reports and a sensor modality that starts lying at contact 20. Two policies decide each contact. This is a visualisation of a host-scored run - the microscope view - not live nodes.
Published results
- Flagship communication result - communication helps, corruption worse than silence
- Cycle-07 trust matrix - forgery and lying-insider policies pass; honest baseline fails its frozen floors
- Kulira trust experiment series - fifteen pre-registered experiments, including the falsified ones
- Source repository